
python如何获取整个网页源码
作者:袖梨
2022-06-24
python如何获取整个网页源码?在本篇文章里小编给大家整理的是关于python获取整个网页源码的方法,需要的用户就来一聚教程网参考一下吧!
1、Python中获取整个页面的代码:
import requests
res = requests.get('https://blog.c*s*d*n.net/yirexiao/article/details/79092355')
res.encoding = 'utf-8'
print(res.text)
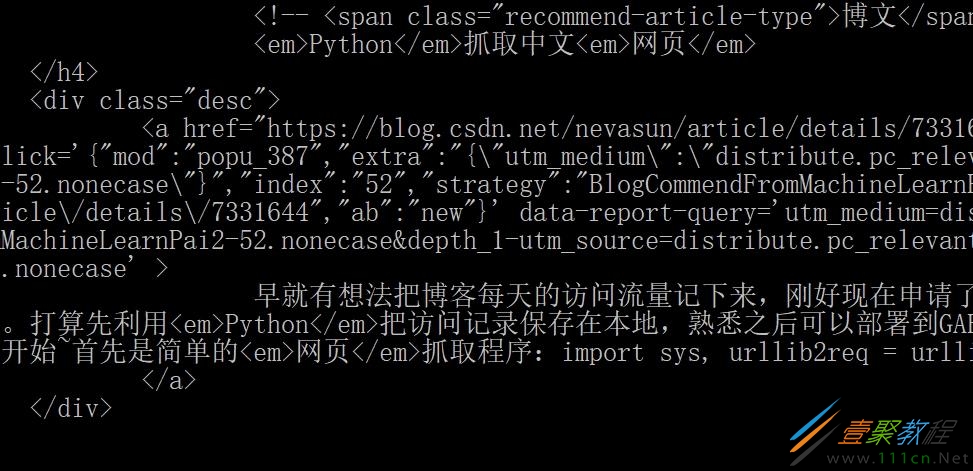
2、运行结果
实例扩展:
from bs4 import BeautifulSoup
import time,re,urllib2
t=time.time()
websiteurls={}
def scanpage(url):
 websiteurl=url
 t=time.time()
 n=0
 html=urllib2.urlopen(websiteurl).read()
 soup=BeautifulSoup(html)
 pageurls=[]
 Upageurls={}
 pageurls=soup.find_all("a",href=True)
 for links in pageurls:
  if websiteurl in links.get("href") and links.get("href") not in Upageurls and links.get("href") not in websiteurls:
   Upageurls[links.get("href")]=0
 for links in Upageurls.keys():
  try:
   urllib2.urlopen(links).getcode()
  except:
   print "connect failed"
  else:
   t2=time.time()
   Upageurls[links]=urllib2.urlopen(links).getcode()
   print n,
   print links,
   print Upageurls[links]
   t1=time.time()
   print t1-t2
  n+=1
 print ("total is "+repr(n)+" links")
 print time.time()-t
scanpage(http://news.16***3.com/)
相关文章
-
DeepSeek多模态怎么样及保姆级配置教程(codex、claude)实用指南
游戏攻略 2026-10-17
-
WSL2+Docker+Ollama本地部署大模型思路和实践指南(Qwen1.8b)实用指南
游戏攻略 2026-10-17
-
DeepSeek Harness热门插件盘点:10个实用插件,覆盖多Agent、上下文和多模态实用指南
游戏攻略 2026-10-17
-
grep文本搜索与正则表达式完整代码示例实用指南
游戏攻略 2026-10-16
-
AI漫剧伪装直男1‑24集无雾版夸克网盘资源免费分享
游戏攻略 2026-10-15
-
AI漫剧玉僧入尘1-68集无雾无删版夸克网盘资源免费分享
游戏攻略 2026-10-15








